Abstract
We present RynnWorld-Latent, a cross-embodiment video world model designed not only for future prediction but also for scalable robot data generation. RynnWorld-Latent addresses the action-label bottleneck by using continuous latent actions as a unified representation of world-state transitions, so human egocentric videos and robot data can be jointly modeled without embodiment-specific control commands. Built on a pretrained video diffusion transformer, it is text-free and introduces explicit frame-aligned action conditioning, enabling precise control over future dynamics while preserving the pretrained video prior. Beyond prediction, it serves as a data-generation engine: conditioned on target robot actions it supports interactive digital teleoperation; conditioned on latent actions it synthesizes new rollouts by editing a source video's first frame and reusing its latent actions.
Key Highlights
- Universal latent-action interface:
One embodiment-agnostic action space lets human, robot and simulation video pretrain a single world model. - Prior-preserving frame-aligned conditioning:
Identity-initialized, frame-aligned injection gives precise action control without overwriting the pretrained video prior. - World model as data engine:
Interactive digital teleoperation and first-frame-editing + latent-action synthesis produce paired action-video data without physical execution.
Training Data
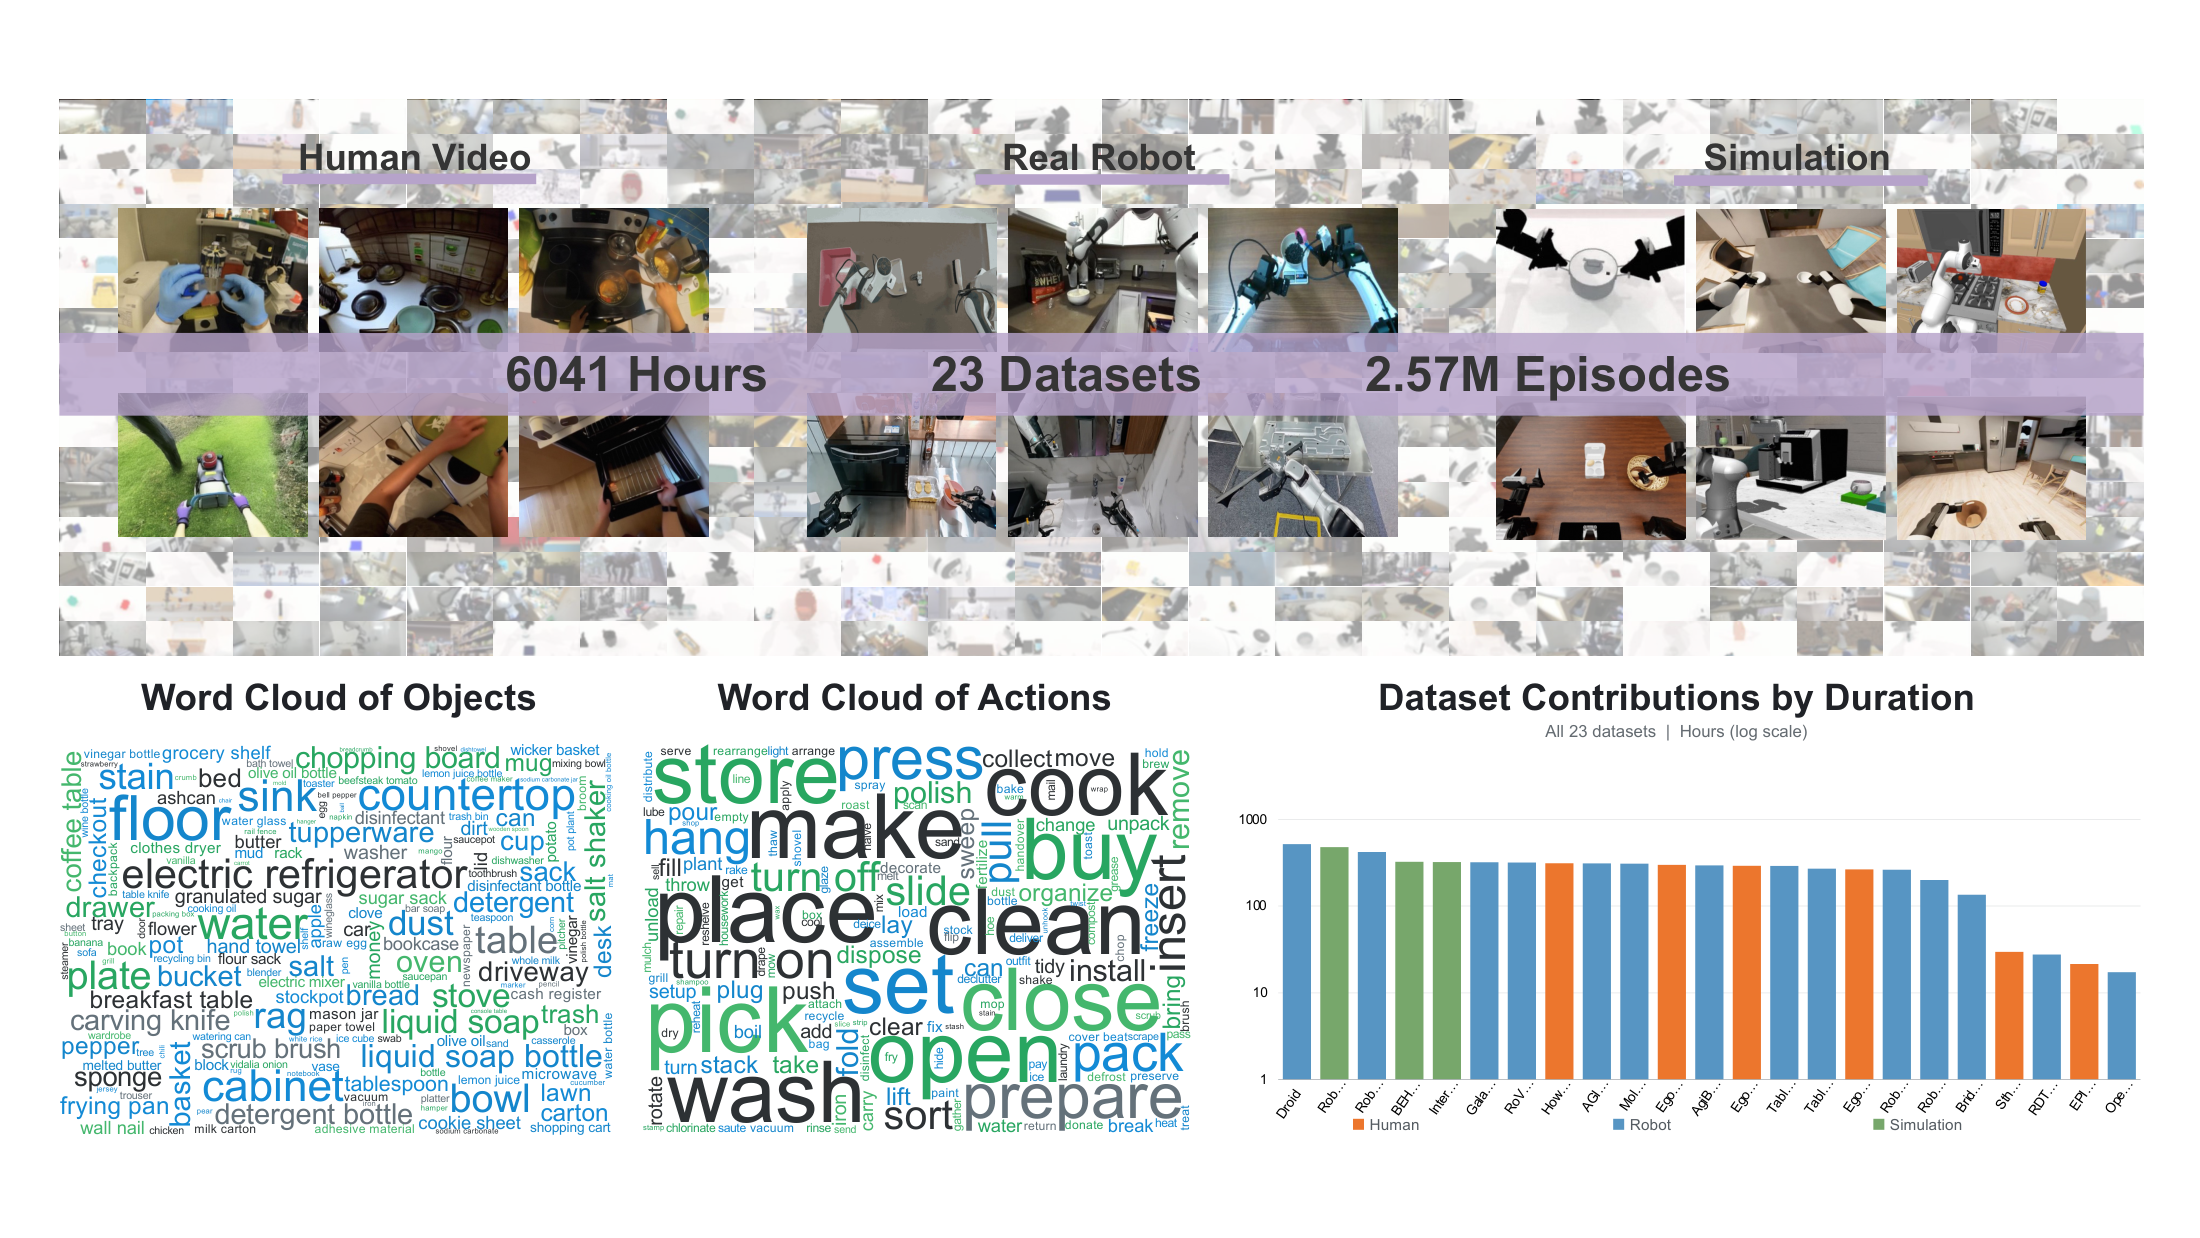
Pre-training corpus of RynnWorld-Latent. Human egocentric video, real-robot teleoperation and simulation rollouts are all relabelled by RynnLAM into one shared latent-action space, giving a single cross-embodiment conditioning signal. Click the figure to enlarge.
Action-Conditioned Video Generation
Given an initial frame and a supplied action sequence, RynnWorld-Latent generates the future rollout. Three embodiments × three rollouts.
Action Following
Each strip is one pair: GT-A | Gen(A frame + A action) | Gen(A frame + B action) | GT-B. Both generations start from the SAME first frame (A's); only the action differs, so the third panel diverging from the second — and matching GT-B's motion — is direct evidence of action following.
First-Frame Editing + Latent-Action Synthesis
Left: the source human-hand video. Right: the rollout generated after editing the first frame to the robot embodiment and reusing the source latent actions.
Results
Open-loop simulation quality on our own real-robot evaluation sets, recorded as ground-truth rollouts on both platforms and held out from post-training (higher PSNR/SSIM and lower LPIPS are better).
| Method | Marvin-WUJI Eval | Astribot-S1 Eval | ||||
|---|---|---|---|---|---|---|
| PSNR↑ | SSIM↑ | LPIPS↓ | PSNR↑ | SSIM↑ | LPIPS↓ | |
| Cosmos3-Edge | 20.03 | 0.78 | 0.31 | 13.99 | 0.42 | 0.54 |
| Cosmos3-Nano | 20.09 | 0.80 | 0.26 | 14.22 | 0.53 | 0.45 |
| RynnWorld-Teleop | 20.89 | 0.76 | 0.19 | N/A | N/A | N/A |
| RynnWorld-Latent | 21.86 | 0.80 | 0.12 | 15.96 | 0.60 | 0.34 |
Open-loop rollout quality on the DreamDojo GR-1 evaluation sets (higher PSNR/SSIM and lower LPIPS is better).
| Model | In-lab Eval | EgoDex Eval | DreamDojo-HV Eval | ||||||
|---|---|---|---|---|---|---|---|---|---|
| PSNR↑ | SSIM↑ | LPIPS↓ | PSNR↑ | SSIM↑ | LPIPS↓ | PSNR↑ | SSIM↑ | LPIPS↓ | |
| Cosmos-Predict2.5 | 20.58 | 0.77 | 0.22 | 19.95 | 0.79 | 0.22 | 18.27 | 0.75 | 0.24 |
| DreamDojo-2B | 21.11 | 0.77 | 0.22 | 20.41 | 0.78 | 0.23 | 18.81 | 0.75 | 0.24 |
| DreamDojo-14B | 21.41 | 0.79 | 0.21 | 20.53 | 0.79 | 0.21 | 18.92 | 0.75 | 0.23 |
| RynnWorld-Latent | 21.42 | 0.82 | 0.20 | 20.89 | 0.81 | 0.19 | 19.22 | 0.79 | 0.21 |
Closed-loop success rate (%) on real-world manipulation tasks, 35 trials each. Bold marks the best within each training-setting block; N/A = not applicable to Astribot-S1 (mobile-base motion not modelled).
| Method | Training Setting | Marvin-WUJI | Astribot-S1 | ||
|---|---|---|---|---|---|
| Plate Placement | Plate Wiping | Steak Serving | Plate Retrieval | ||
| Digital teleoperation | |||||
| π0 | Real only | 80.00 | 71.43 | 37.14 | 45.71 |
| π0 | Real + Digital Teleop | 88.57 | 94.29 | 51.43 | 51.43 |
| π0.5 | Real only | 82.86 | 77.14 | 40.00 | 45.71 |
| π0.5 | Digital Teleop only | 57.14 | 54.29 | 28.57 | 31.43 |
| π0.5 | Real + RynnWorld-Teleop | 85.71 | 82.86 | N/A | N/A |
| π0.5 | Real + Digital Teleop | 91.43 | 91.43 | 54.29 | 57.14 |
| Large-scale synthetic mid-training | |||||
| π0 | RynnWorld-80M + Real | 85.71 | 82.86 | 48.57 | 54.29 |
| π0.5 | Real + Ego2Robot | 88.57 | 91.43 | N/A | N/A |
| π0.5 | RynnWorld-80M + Real | 94.29 | 97.14 | 60.00 | 68.57 |
BibTeX
@article{rynnworld2026latent,
  title   = {RynnWorld-Latent: A Cross-Embodiment World Model Conditioned on Universal Latent Actions},
  author  = {Haoyu Zhao and Yinzhou Tang and Zixuan Wang and Minghao Zhu and Dongchi Huang and Xingyue Zhao and Qin Zhao and Kehan Li and Siteng Huang and Xin Li and Zhongyu Li},
  year    = {2026}
}