Real-Robot Demos
YouTube: 观看链接
Abstract
Vision-language-action (VLA) models are limited by the scarcity and fragmentation of action-annotated robot data: different embodiments define incompatible action spaces, while abundant human videos remain unusable because they lack action labels. We present a unified latent-action framework that turns heterogeneous manipulation video into a shared, embodiment-agnostic action space. We first train RynnLAM, a latent action model, fully self-supervised to compress inter-frame dynamics into compact latent actions grounded in physical motion. Using RynnLAM as a scalable auto-labeler we densely annotate a large multi-source corpus, then pretrain RynnVLA-Latent, a Mixture-of-Transformers VLA that generates latent-action chunks from language and multi-view observations via flow matching; post-training retargets the same objective to robot-specific action spaces, requiring action-labeled demonstrations only for final embodiment alignment.
Key Highlights
- Metric, 3D, camera-invariant latent actions:
RynnLAM grounds latents in future visual features, dynamic 3D flow and explicit camera-ego-motion decoupling. - Label once, align everything:
One shared latent-action space absorbs robot, simulation and human egocentric video under a single supervision signal. - Pretrain then retarget:
Flow-matching pretraining on latent actions, then post-training retargets the same objective to the target robot's action space with no extra decoder.
Overview
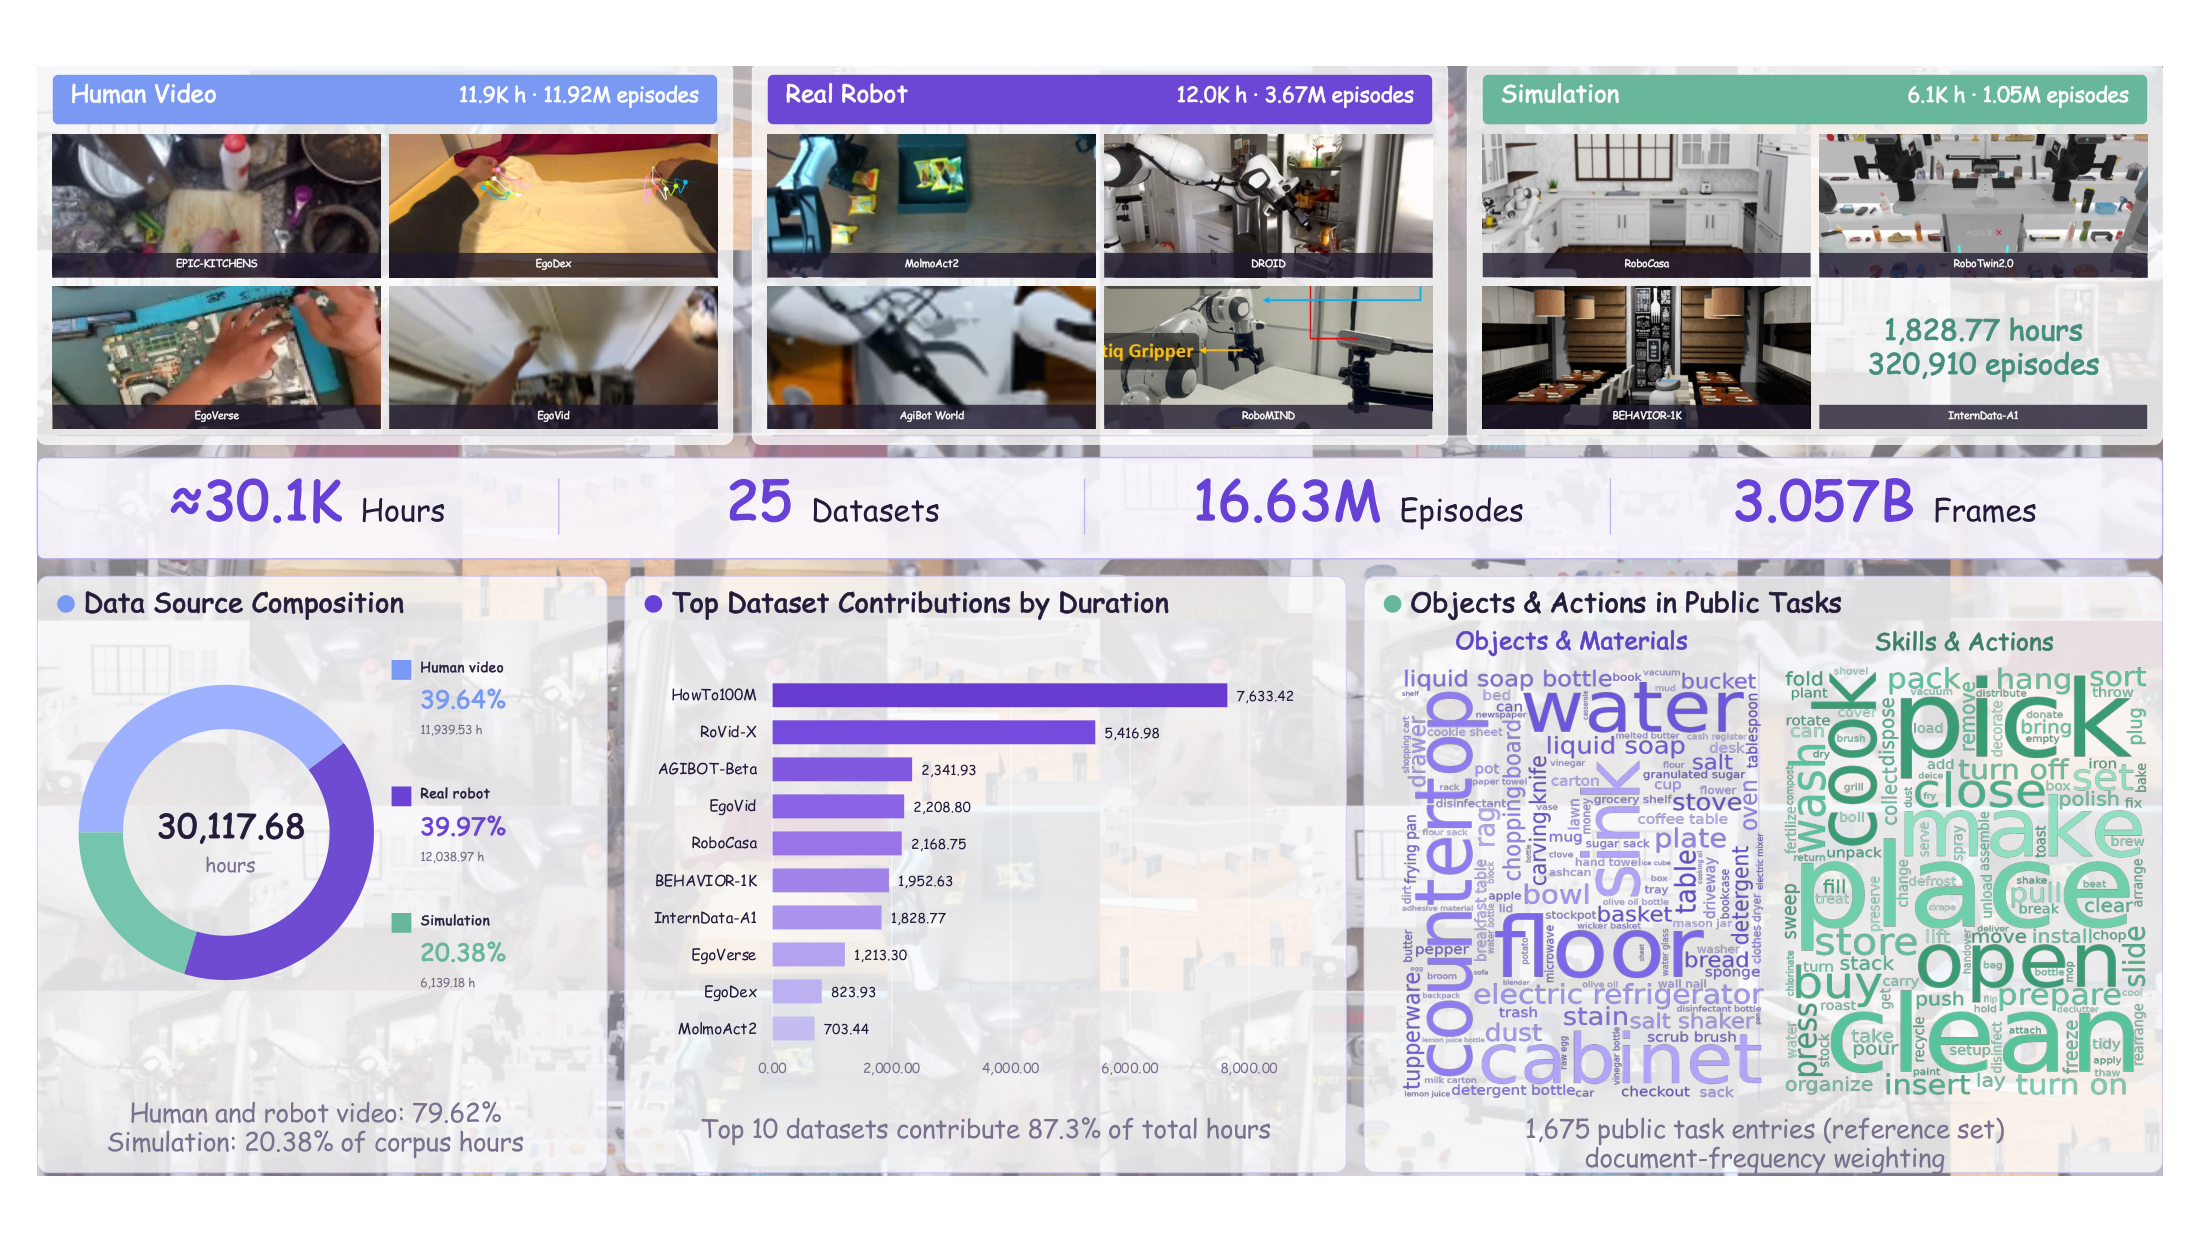
2 · Auto-labeling. RynnLAM annotates a 25-dataset multi-embodiment corpus into one shared latent-action space.
3 · Pretraining. A Mixture-of-Transformers policy (RynnBrain VLM + narrow action expert) generates latent-action chunks via flow matching.
4 · Post-training. The same flow-matching objective is retargeted to the target robot’s action space; no separate decoder is added.
Training Data
Pre-training corpus of RynnVLA-Latent. Human egocentric video, real-robot manipulation and simulation rollouts are all relabelled by RynnLAM into one shared latent-action space, so heterogeneous sources contribute to a single policy objective. Click the figure to enlarge.
Results
Full evaluation from the paper: latent-action representation quality (LARY), simulation benchmarks (LIBERO, LIBERO-Plus, RoboTwin 2.0, VLABench) and six real-world tasks. Best per column is highlighted.
| Method | Avg. | CALVIN | VLABench | RoboCOIN | AgiBotWorld-B |
|---|---|---|---|---|---|
| General Encoders (Absolute Action) | |||||
| V-JEPA 2 | 0.25 | 0.27 | 0.07 | 0.32 | 0.33 |
| DINOv3 | 0.19 | 0.22 | 0.06 | 0.22 | 0.24 |
| Wan2.2 | 0.30 | 0.39 | 0.09 | 0.34 | 0.39 |
| FLUX.2-dev | 0.35 | 0.25 | 0.04 | 0.47 | 0.62 |
| RynnLAM (Raw Features) | 0.14 | 0.08 | 0.01 | 0.24 | 0.22 |
| Embodied LAMs (Absolute Action) | |||||
| LAPA | 0.97 | 0.96 | 0.95 | 0.96 | 1.00 |
| Moto | 0.67 | 0.24 | 0.60 | 0.88 | 0.97 |
| UniVLA | 0.87 | 0.82 | 0.74 | 0.94 | 0.97 |
| villa-X | 0.87 | 0.86 | 0.72 | 0.94 | 0.97 |
| DreamDojo | 0.49 | 0.34 | 0.14 | 0.74 | 0.74 |
| RynnLAM | 0.27 | 0.34 | 0.01 | 0.34 | 0.39 |
| Embodied LAMs (Relative Action) | |||||
| LAPA | 0.93 | 0.72 | 1.00 | 1.01 | 0.98 |
| Moto | 0.77 | 0.65 | 0.64 | 0.91 | 0.89 |
| DreamDojo | 0.55 | 0.35 | 0.33 | 0.81 | 0.70 |
| RynnLAM | 0.38 | 0.40 | 0.05 | 0.42 | 0.64 |
| Method | Spatial | Object | Goal | Long | Avg |
|---|---|---|---|---|---|
| OpenVLA-OFT | 97.6 | 98.4 | 97.9 | 94.5 | 97.1 |
| π0-FAST | 96.4 | 96.8 | 88.6 | 60.2 | 85.5 |
| π0 | 98.0 | 96.8 | 94.4 | 88.4 | 94.4 |
| π0.5 | 98.8 | 98.2 | 98.0 | 92.4 | 96.9 |
| GR00T-N1.7 | 97.7 | 98.5 | 97.5 | 94.4 | 97.0 |
| InternVLA-M1 | 98.0 | 99.0 | 93.8 | 92.6 | 95.9 |
| Motus | 96.8 | 99.8 | 96.6 | 97.6 | 97.7 |
| Fast-WAM | 98.2 | 100.0 | 97.0 | 95.2 | 97.6 |
| Xiaomi-Robotics-0 | 98.8 | 100.0 | 98.8 | 97.2 | 98.7 |
| LingBot-VA | 98.5 | 99.6 | 97.2 | 98.5 | 98.5 |
| RynnVLA-Latent-2B | 98.6 | 99.6 | 97.0 | 97.8 | 98.3 |
| RynnVLA-Latent-4B | 99.4 | 99.8 | 98.8 | 97.0 | 98.8 |
| Method | Cam | Robot | Lang | Light | Bkg | Noise | Layout | Total |
|---|---|---|---|---|---|---|---|---|
| OpenVLA | 0.8 | 3.5 | 23.0 | 8.1 | 34.8 | 15.2 | 28.5 | 15.6 |
| OpenVLA-OFT | 56.4 | 31.9 | 79.5 | 88.7 | 93.3 | 75.8 | 74.2 | 69.6 |
| π0 | 13.8 | 6.0 | 58.8 | 85.0 | 81.4 | 79.0 | 68.9 | 53.6 |
| π0-FAST | 65.1 | 21.6 | 61.0 | 73.2 | 73.2 | 74.4 | 68.8 | 61.6 |
| π0.5 | 78.4 | 73.6 | 80.8 | 96.2 | 94.1 | 89.0 | 84.5 | 84.4 |
| StarVLA | 52.5 | 49.8 | 88.5 | 95.7 | 95.7 | 73.0 | 76.9 | 74.1 |
| ABot-M0 | 60.4 | 67.9 | 86.4 | 96.2 | 91.6 | 86.4 | 82.6 | 80.5 |
| Cosmos Policy | 75.8 | 63.3 | 81.7 | 96.5 | 88.9 | 92.7 | 82.2 | 82.2 |
| RynnVLA-Latent-2B | 76.4 | 59.3 | 88.3 | 96.2 | 94.6 | 89.6 | 83.2 | 82.9 |
| RynnVLA-Latent-4B | 72.9 | 64.0 | 91.7 | 97.1 | 95.4 | 93.2 | 85.2 | 84.7 |
| Method | Clean | Randomized | Avg |
|---|---|---|---|
| π0 | 65.9 | 58.4 | 62.2 |
| π0.5 | 82.7 | 76.8 | 79.8 |
| X-VLA | 72.9 | 72.8 | 72.9 |
| StarVLA-FAST | 72.5 | 83.2 | 77.9 |
| ABot-M0 | 86.1 | 85.1 | 85.6 |
| LingBot-VLA | 88.6 | 86.7 | 87.7 |
| RynnVLA-Latent-2B | 87.9 | 87.2 | 87.6 |
| RynnVLA-Latent-4B | 88.7 | 88.4 | 88.6 |
| Method | In-Dist (SR/PS/IS) | Cross-Cat | Common Sense | Semantic Instr. | Unseen Texture | Average | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| π0 | 47.0 | 62.7 | 67.8 | 21.2 | 33.6 | 44.0 | 29.1 | 43.0 | 54.9 | 17.3 | 38.7 | 58.0 | 32.2 | 42.5 | 50.6 | 29.4 | 44.1 | 55.0 |
| π0-FAST | 56.2 | 66.8 | 72.4 | 31.0 | 38.2 | 47.8 | 38.0 | 48.6 | 56.8 | 35.0 | 45.0 | 59.4 | 39.0 | 49.0 | 56.8 | 39.8 | 49.5 | 58.6 |
| π0.5 | 65.4 | 77.8 | 80.4 | 38.2 | 49.7 | 52.0 | 43.9 | 57.3 | 60.0 | 48.2 | 64.2 | 67.0 | 44.9 | 62.3 | 65.0 | 48.1 | 62.3 | 64.9 |
| RynnVLA-Latent-2B | 58.5 | 71.2 | 81.2 | 30.3 | 40.1 | 53.3 | 26.2 | 39.9 | 59.8 | 34.0 | 51.0 | 73.0 | 37.1 | 50.7 | 74.5 | 37.2 | 50.6 | 68.4 |
| RynnVLA-Latent-4B | 67.8 | 80.3 | 83.9 | 48.0 | 60.7 | 68.2 | 44.6 | 53.8 | 54.1 | 53.0 | 69.8 | 71.1 | 45.9 | 62.1 | 72.9 | 51.9 | 65.3 | 70.0 |
| Model | Plate Placement | Steak Cooking | Plate Wiping | Table Cleaning | Steak Serving | Plate Retrieval |
|---|---|---|---|---|---|---|
| π0 | 80.00 | 34.29 | 71.43 | 22.86 | 37.14 | 45.71 |
| π0.5 | 82.86 | 28.57 | 77.14 | 25.71 | 40.00 | 45.71 |
| GR00T-N1.7 | 74.29 | 28.57 | 74.29 | 17.14 | 45.71 | 37.14 |
| RynnVLA-Latent-2B | 80.00 | 34.29 | 68.57 | 34.29 | 42.86 | 48.57 |
| RynnVLA-Latent-4B | 85.71 | 42.86 | 82.86 | 40.00 | 57.14 | 54.29 |
Visualizations
Qualitative analysis from the paper. Click any figure to enlarge.
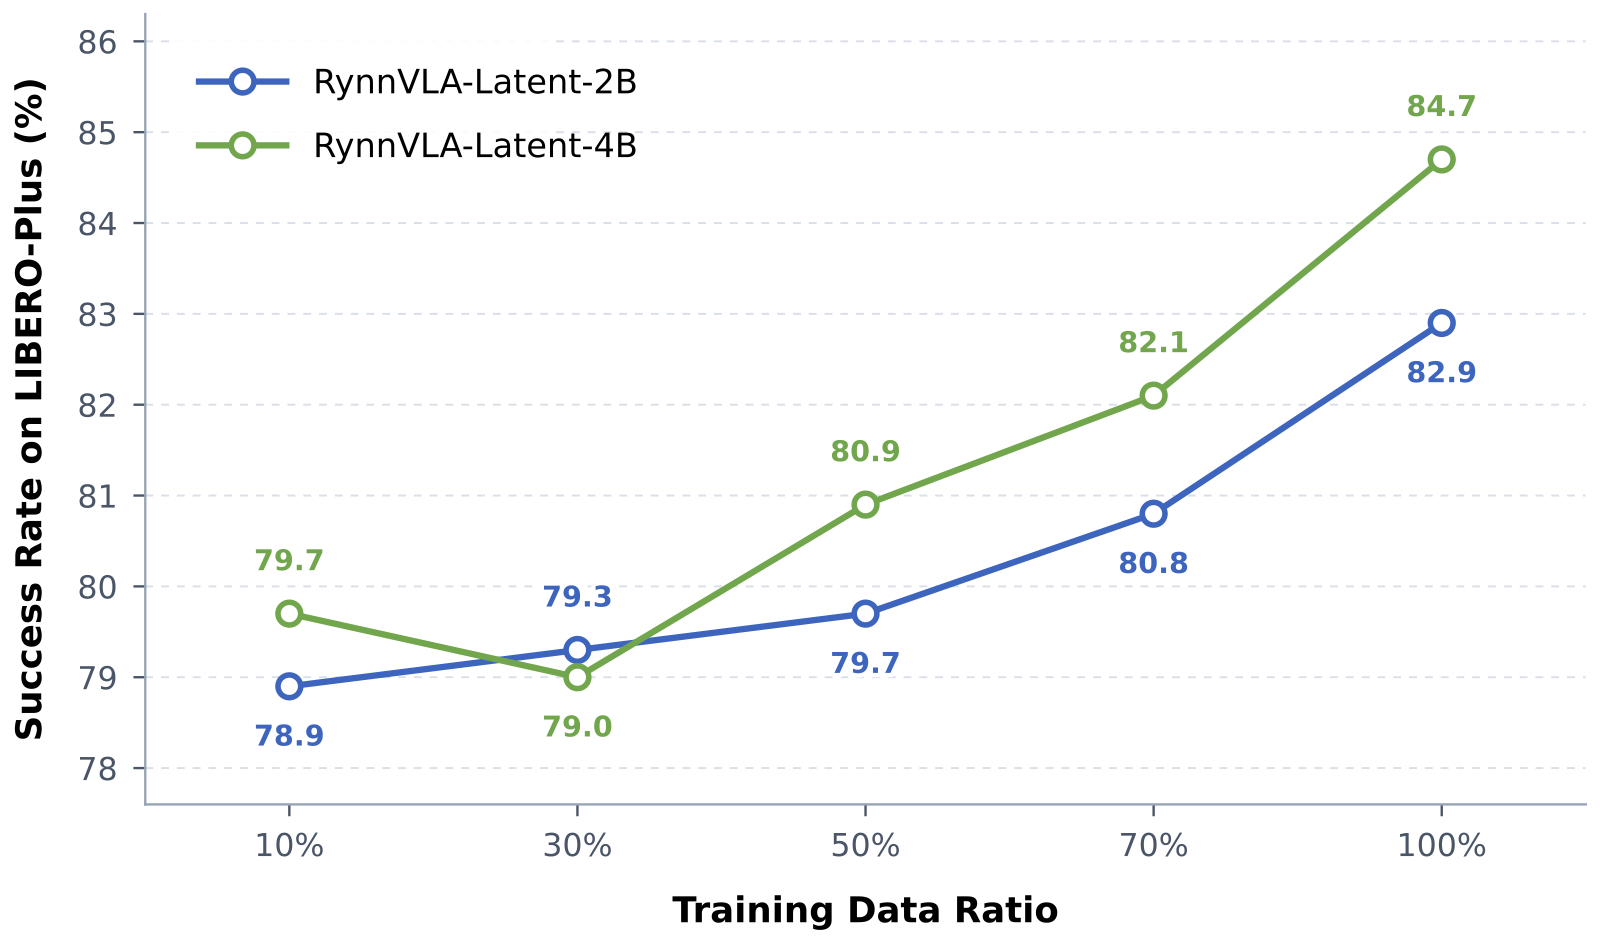
RynnVLA-Latent-2B / 4B pretrained with 10%–100% of the latent-action corpus and evaluated on LIBERO-Plus: both variants reach their highest success rates on the full corpus.
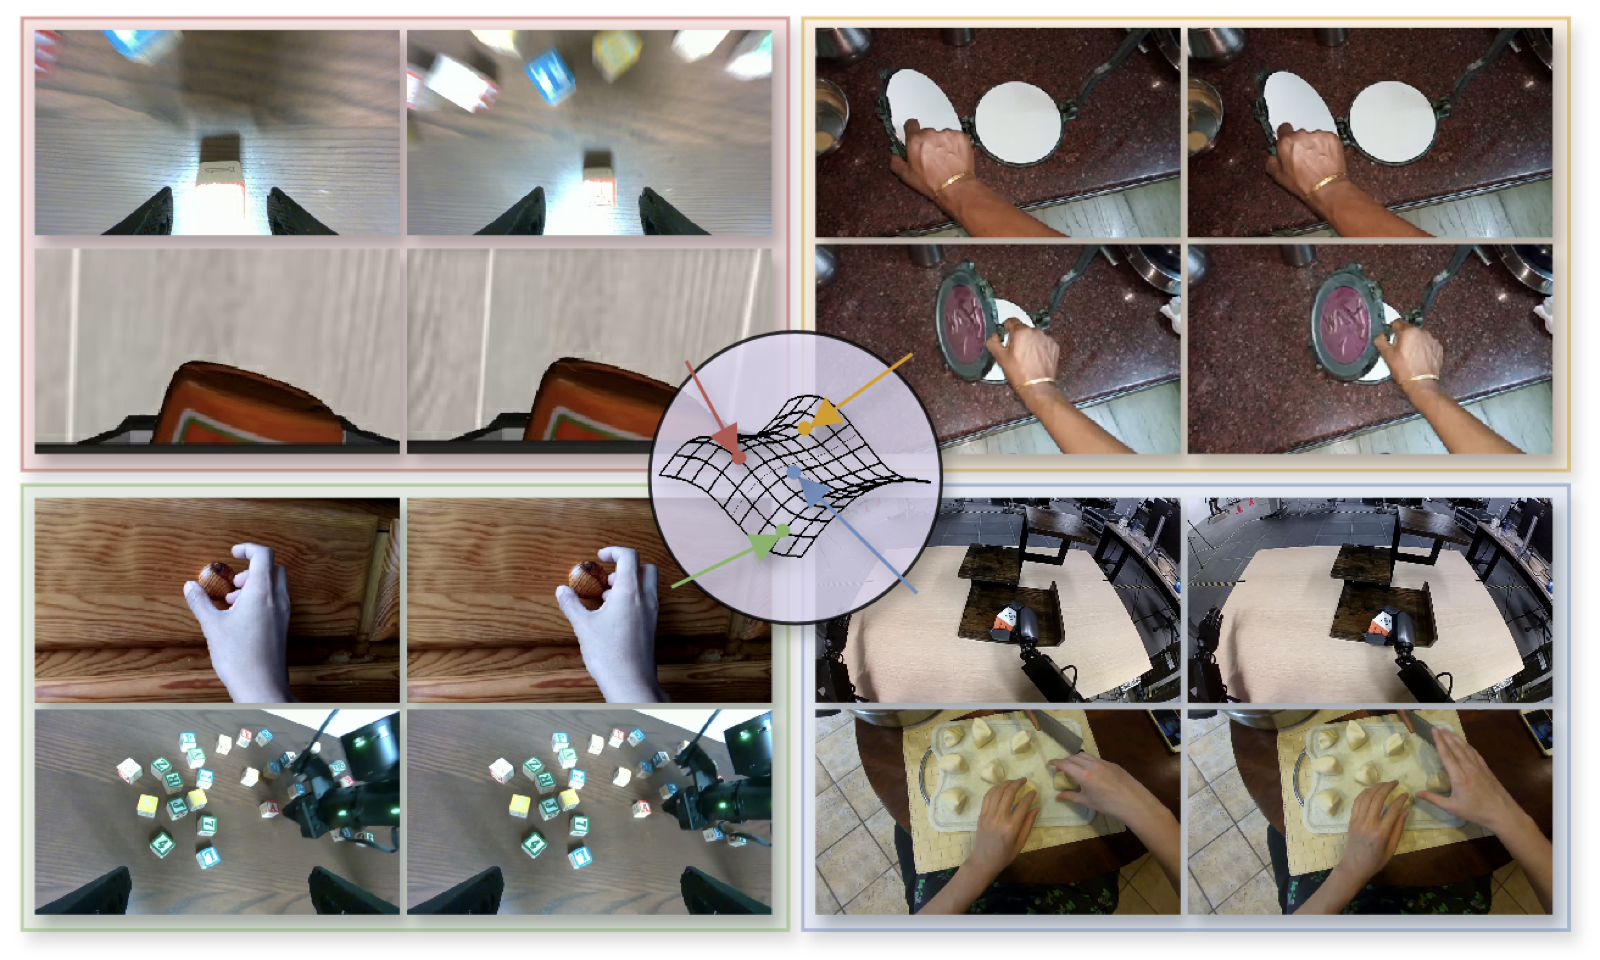
Nearest neighbors of query latent actions retrieved across the multi-embodiment corpus: high-similarity neighbors exhibit related motion patterns across different embodiments and visual domains.
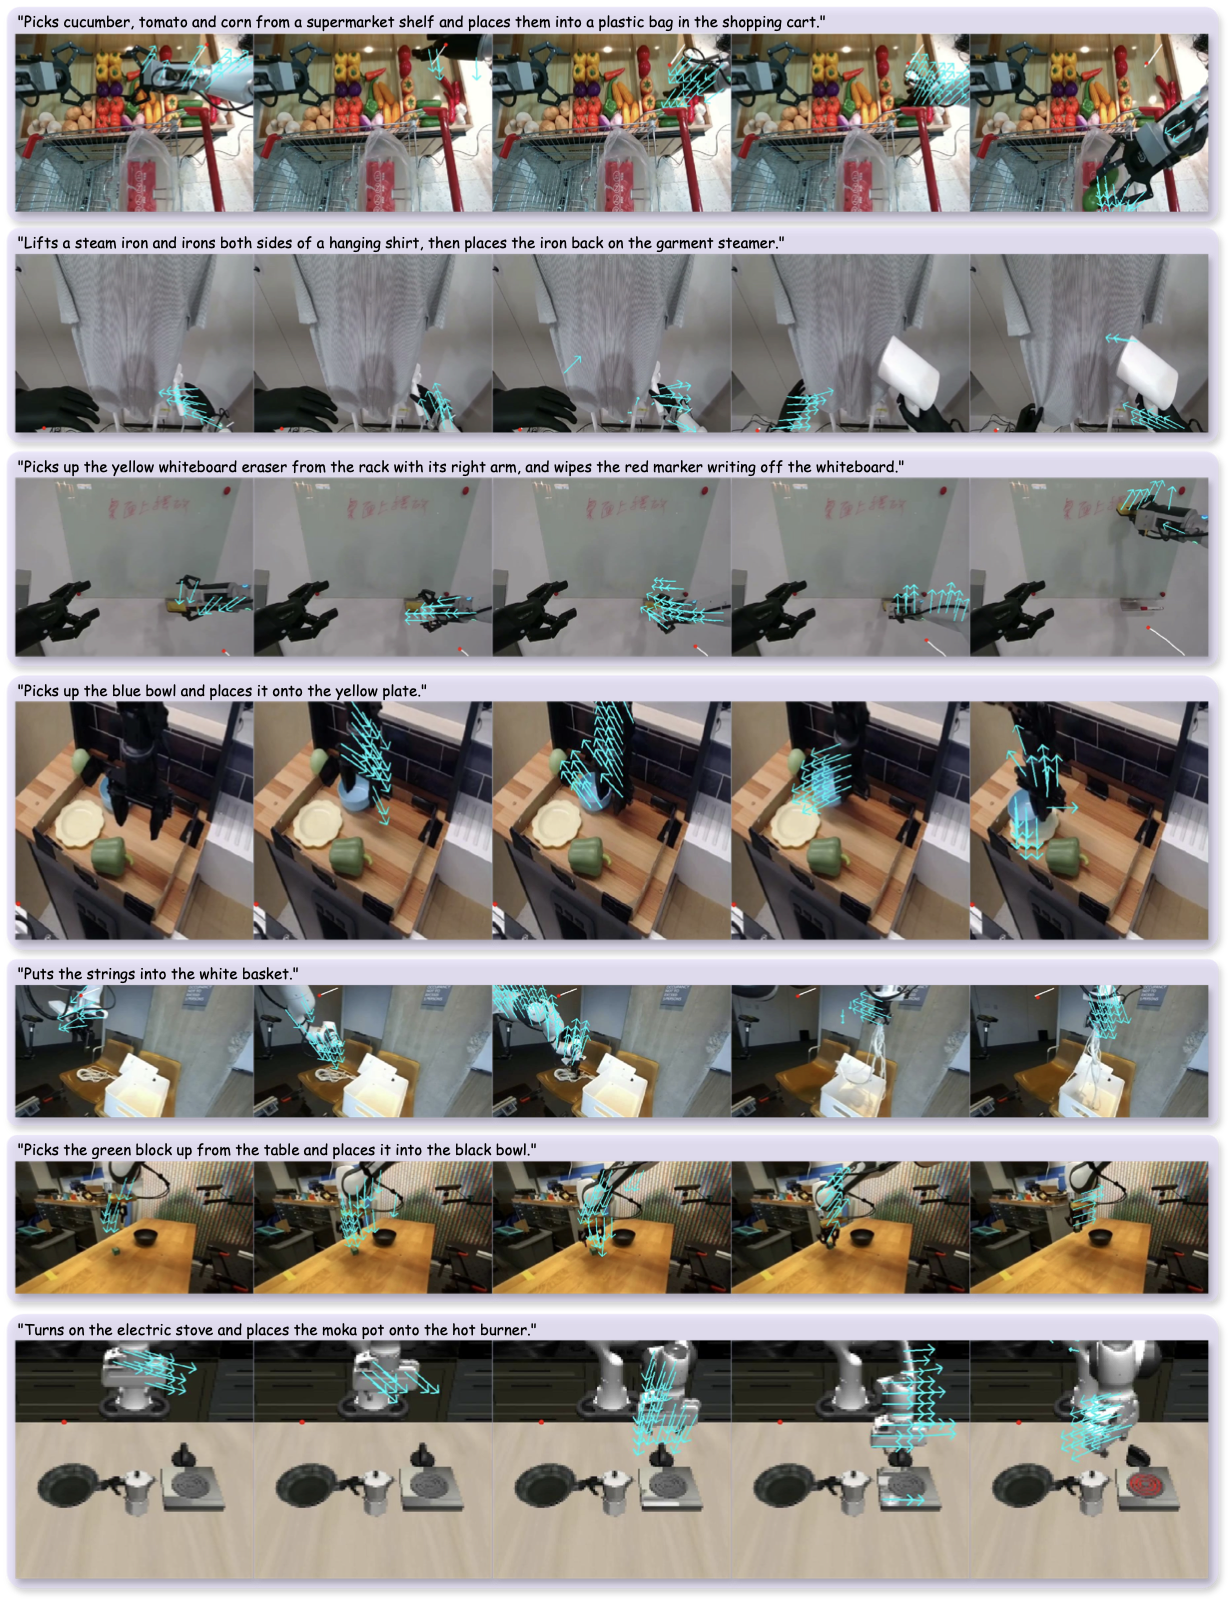
Given the current observation and instruction, RynnVLA-Latent predicts a latent-action chunk that is fed into the frozen RynnLAM 3D-flow decoder, visualizing the motion implied by the latent predictions.
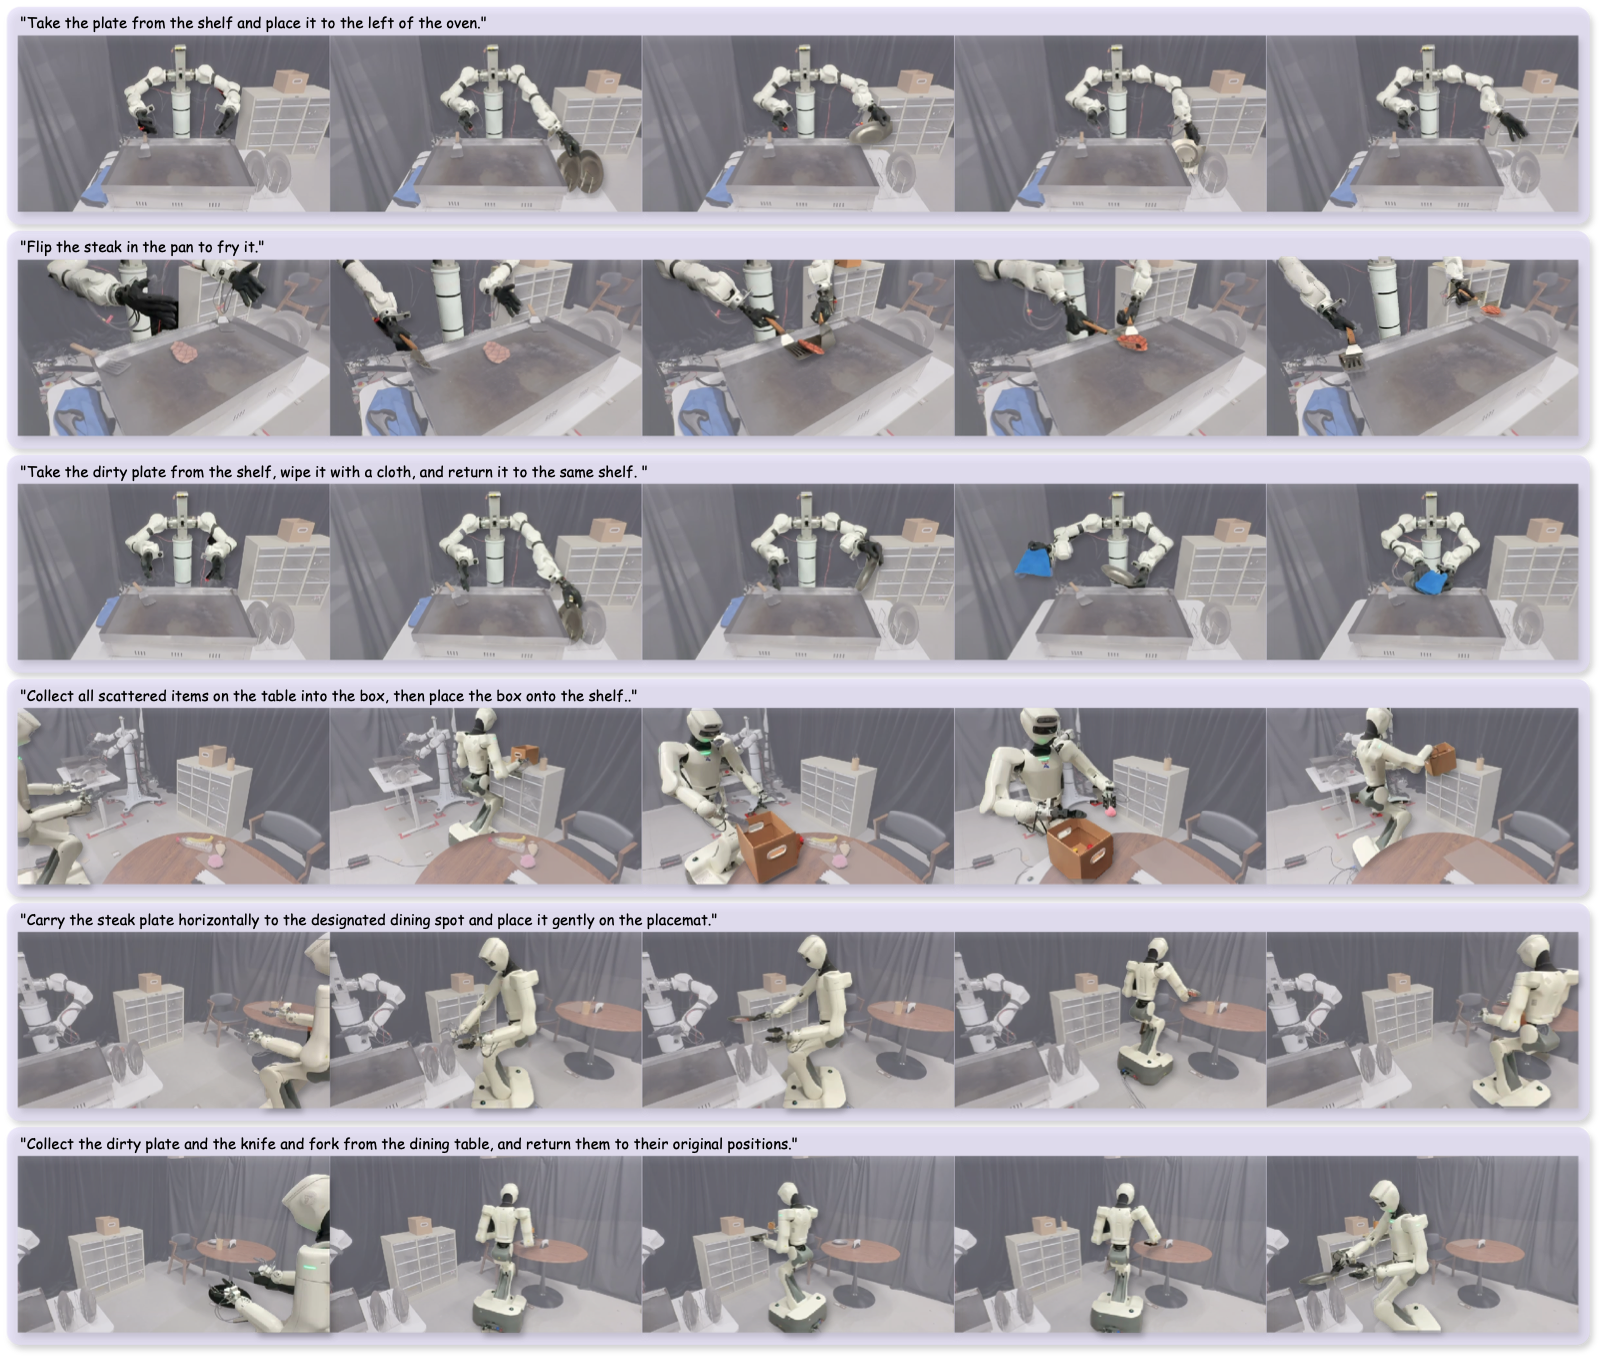
Representative executions of the six post-trained real-world tasks on Marvin-WUJI (dual-arm dexterous hands) and Astribot-S1 (wheeled mobile dual-arm grippers).
BibTeX
@article{rynnvla2026latent,
  title   = {RynnVLA-Latent: Latent Action Pretraining for Robotic Manipulation Foundation Models},
  author  = {Haoyu Zhao and Xingyue Zhao and Zhian Su and Bohan Hou and Yinzhou Tang and Fengyi Wang and Kehan Li and Yuming Jiang and Siteng Huang and Xin Li and Zhenyu Zeng and Mingxiu Chen and Deli Zhao and Zhongyu Li},
  year    = {2026}
}